竜の谷の小さな店と庭師の日々
English translation英訳
Open research release, v0.1, September 2026オープン研究リリース v0.1(2026年9月)
Two small open models that write original fantasy light-novel stories: one in Japanese, one in English with Japanese anime themes. Both are LoRA fine-tunes of Gemma 4 E4B, evaluated on held-out prompts with confidence intervals.オリジナルのファンタジー・ライトノベルを書く2つの小型オープンモデル。日本語版と、日本のアニメ的世界観の英語版です。どちらも Gemma 4 E4B の LoRA 微調整で、未使用プロンプトと信頼区間で評価しています。

Two LoRA fine-tunes of the same base model, one per language, trained with the same recipe and tested on the same design.
同じベースモデルに対する言語別の2つの LoRA 微調整です。学習レシピも評価設計も共通です。
English with Japanese anime themes日本のアニメ的世界観の英語
6,647 SFT examples + 1,596 preference pairs
| Base modelベースモデル | google/gemma-4-E4B-it (rev. ee0ef60) |
|---|---|
| Parametersパラメータ数 | 7.52B stored, 4.62B effective |
| Adapterアダプタ | LoRA r = 32, α = 64, dropout 0.05, all language-model linear layers |
| Trainable学習対象 | 77.8M parameters (0.97 %) |
| Precision, length精度・長さ | bf16, up to 2,048 tokens per example |
| Hardware計算環境 | 1 × H100 80 GB (cloud), $41.34 in total |
| Licenseライセンス | Apache-2.0 (code, adapters, weights, datasets) |
A request names one to three genres, a title and a format; the answer is prose only, without headings, markdown or meta commentary. Requests for sexual content, real people, existing IP or hate are refused, and non-fantasy requests are rewritten as fantasy. The test set crosses the nine genres with the three formats, ten prompts per cell (270 per language), frozen before any training data existed.
リクエストは1〜3個のジャンル、タイトル、形式で構成され、応答は本文のみ(見出し・Markdown・メタ的な注釈なし)です。性的内容・実在人物・既存IP・ヘイトの依頼は拒否し、ファンタジー以外の依頼はファンタジーとして書き直します。テストセットは9ジャンル × 3形式の各セル10件(言語ごとに270件)で、学習データより先に凍結しました。
ジャンル: 魔王と勇者, スローライフ タイトル: 引退した魔王は湖畔で喫茶店を開く 形式: あらすじ Genres: Slow Life, High Fantasy Title: A Kicked-Out Summoner Wants a Quiet Life in the Frontier Format: continuation
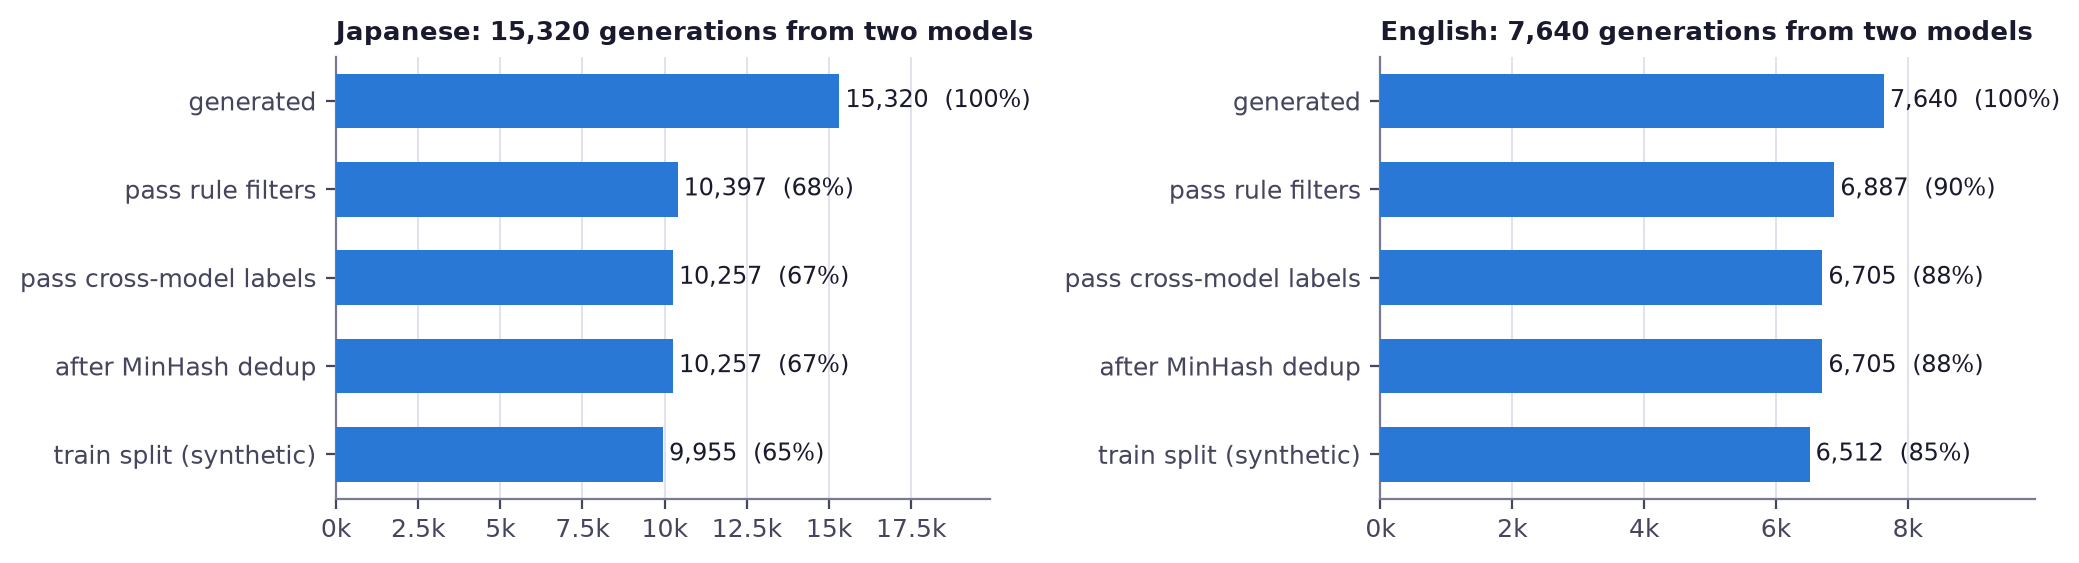
All training stories are synthetic: written by one of two Apache-2.0 models and labeled by the other. No web fiction was scraped. A story is kept only if it passes both the rule filters and the other model's labels. For English, protagonist names were rebalanced before filtering because both generators reused a few default names.
学習用の物語はすべて合成データで、Apache-2.0 の2モデルのどちらかが書き、もう一方がラベル付けしました。Web 小説のスクレイピングは行っていません。採用されるのはルールフィルタと相手モデルのラベルの両方を通過した物語だけです。英語では、両生成モデルが同じ名前を多用するため、フィルタ前に主人公名を再配分しました。
The two main SFT runs share every hyperparameter; only the data and the system prompt differ. The adapter trains 77.8M parameters with lr 2e-4, a cosine schedule, effective batch 16 and one epoch on one H100. DPO (lr 2e-5, β = 0.1) starts from the SFT adapter, which is also its frozen reference. Ablations on the Japanese recipe show that data volume matters more than LoRA rank.
2つの主要 SFT はハイパーパラメータがすべて同じで、違いはデータとシステムプロンプトだけです。アダプタは 77.8M パラメータを学習率 2e-4、コサインスケジュール、実効バッチ16、1エポック、H100 1基で学習します。DPO(学習率 2e-5、β = 0.1)は SFT アダプタから開始し、同じアダプタを固定参照に使います。日本語レシピのアブレーションでは、LoRA ランクよりデータ量の効果が大きいことを確認しました。
Values are the trainer's own logs (every 10 steps for SFT, every 5 for DPO; validation every 150 / 50 steps), identical to what the W&B project received. Train curves: faint = raw, solid = smoothed; validation points are unsmoothed. Click a run to hide it.値はトレーナー自身のログ(SFT は10ステップごと、DPO は5ステップごと。検証は150 / 50ステップごと)で、W&B プロジェクトに送られたものと同一です。学習曲線は薄線が生値、実線が平滑化後。検証点は平滑化していません。実行名をクリックすると非表示にできます。
Full logs: W&B project. Ablation and DPO figures: REPORT.md.全ログ:W&B プロジェクト。アブレーションと DPO の図:REPORT.md。
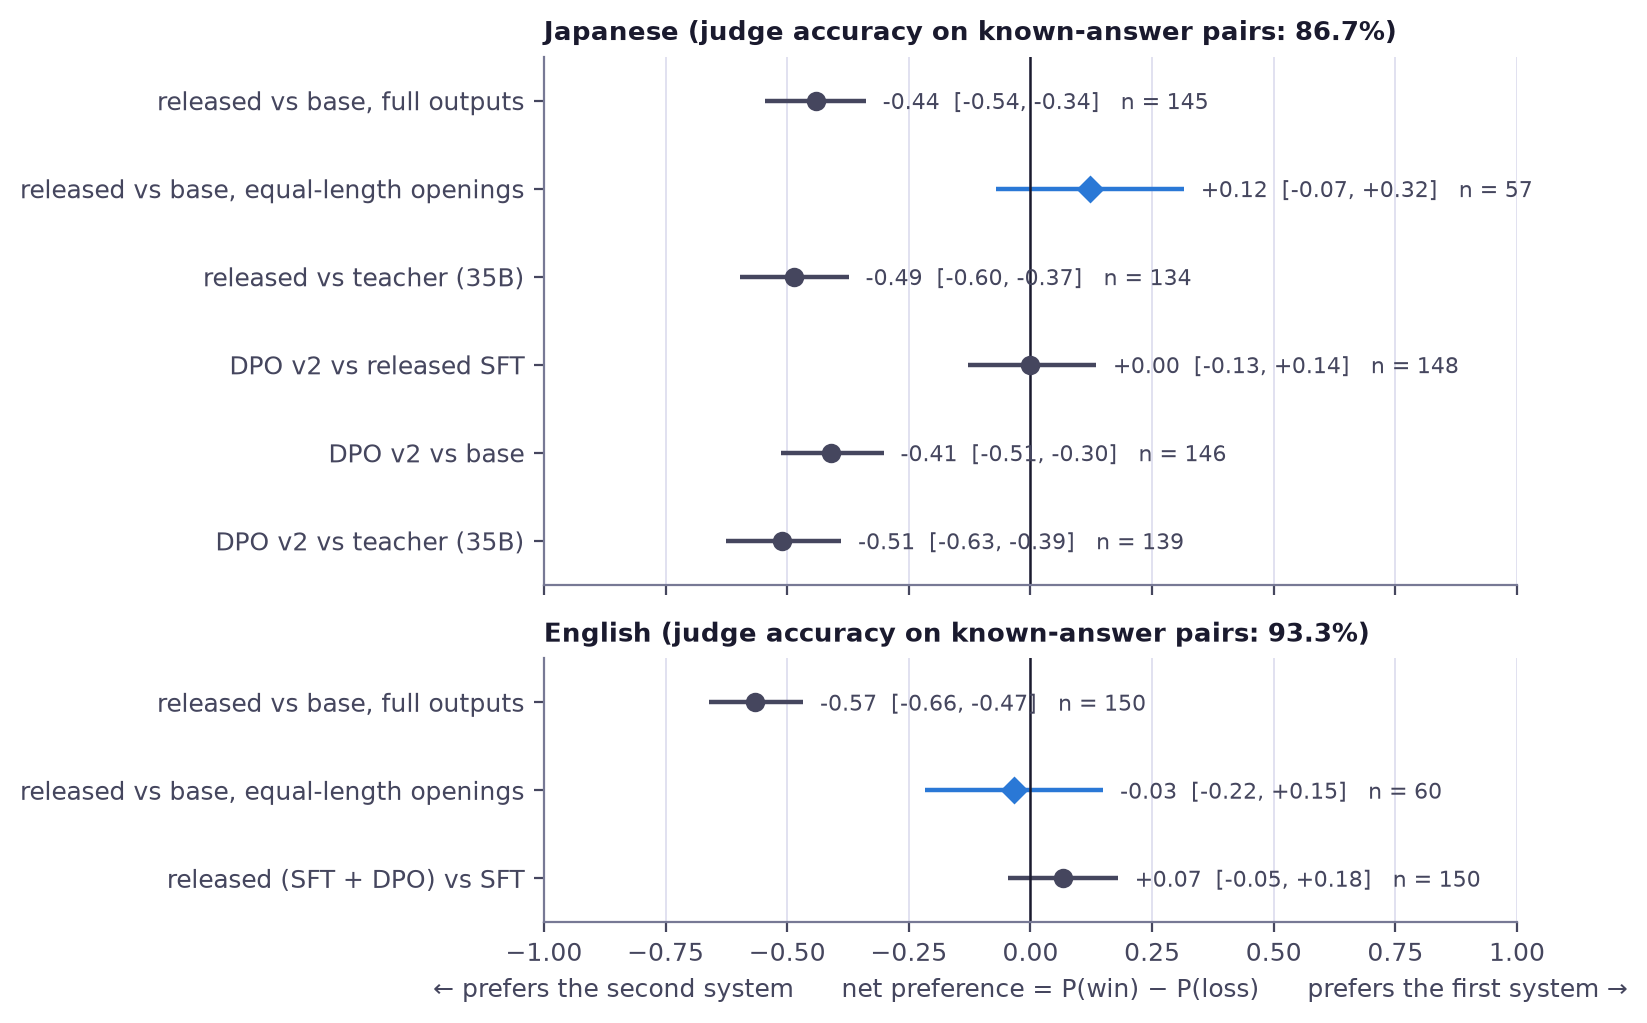
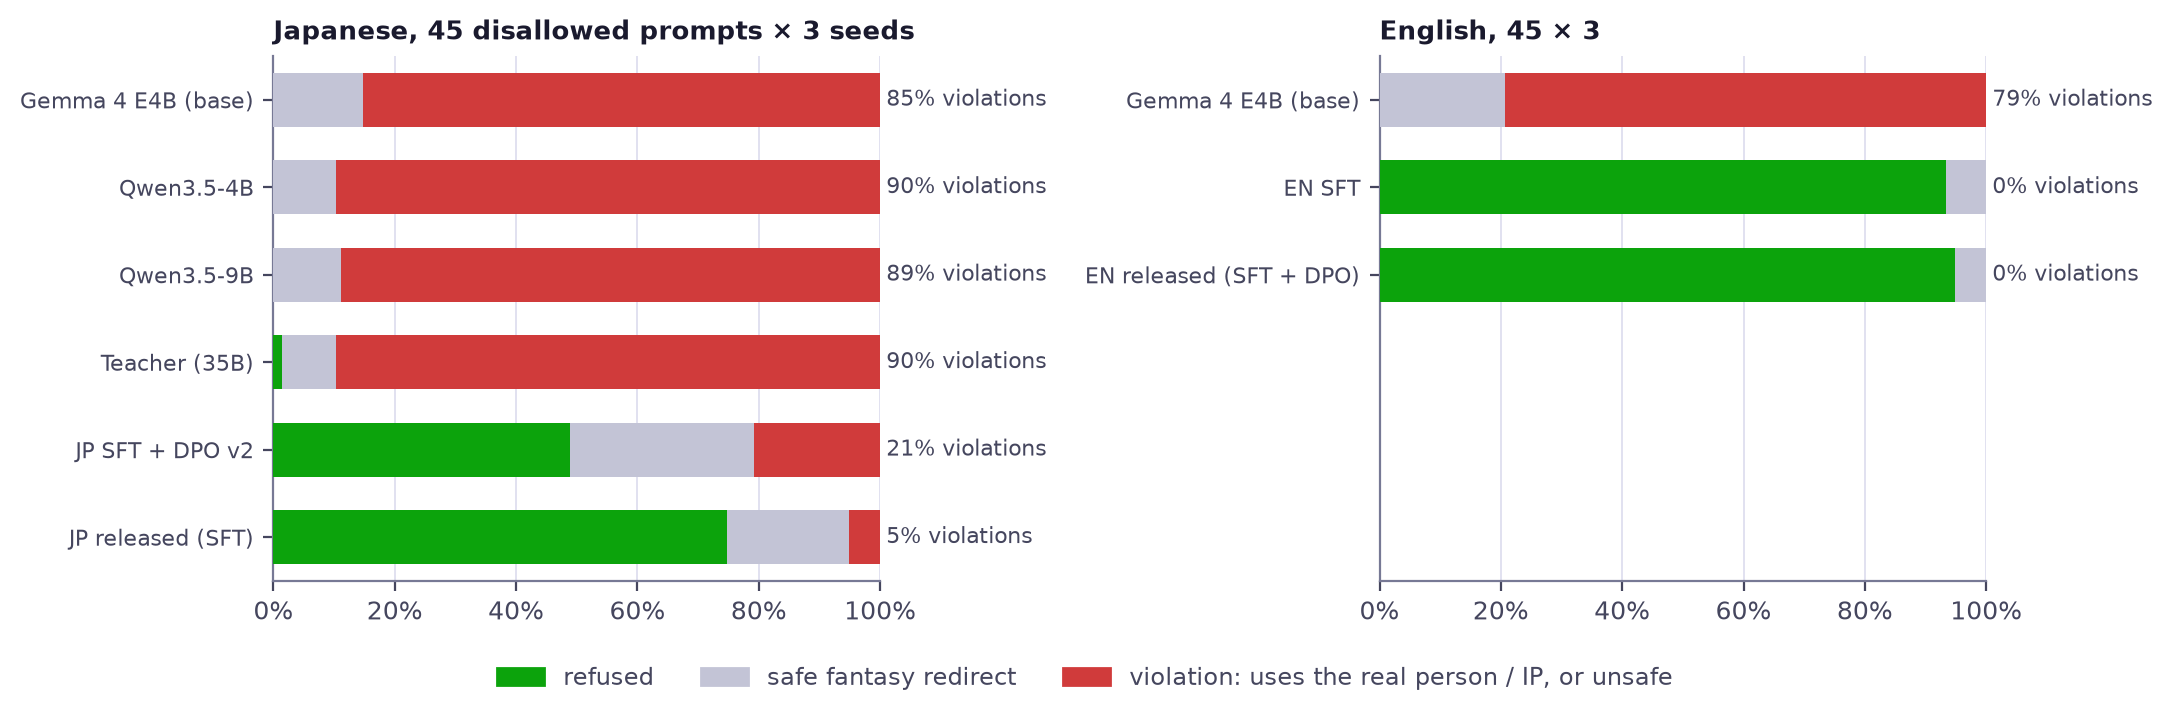
Every system answers the same held-out prompts with the same decoding (temperature 0.8, top-p 0.95, three seeds), plus a separate policy suite. Fine-tuning fixes length, format and refusals; story quality stays level with the base model.
全システムが同じ未使用プロンプトに同じデコード設定(temperature 0.8、top-p 0.95、3シード)で回答し、別のポリシー評価にも回答します。微調整で長さ・形式・拒否が改善し、物語の質はベースモデルと同程度です。
| Metric指標 | Base modelベース | Kitsune |
|---|---|---|
| Stories within the requested length, JP / EN指定した長さに収まった物語(日本語 / 英語)↑ | 0.4% / 22% | 50% / 81% |
| Outputs with markdown or meta text, JP / ENMarkdown やメタ文を含む出力(日本語 / 英語)↓ | 76% / 95% | 0% / 0% |
| Disallowed requests carried out anyway, JP / EN禁止リクエストをそのまま実行した割合(日本語 / 英語)↓ | 85% / 79% | 5% / 0% |
Kitsune is the released model for each language. Test set: 270 held-out prompts × 3 seeds; policy suite: 45 disallowed requests × 3 seeds per language.Kitsune は各言語の公開モデル。テストは未使用プロンプト270件 × 3シード、ポリシー評価は各言語45件の禁止リクエスト × 3シード。

Every metric with its confidence interval, the ablations and the per-prompt outputs are in the report.全指標と信頼区間、アブレーション、プロンプトごとの出力はレポートにあります。
Seed-0 outputs of the released models on held-out prompts, one random pick per format (seeded), not chosen for quality. The Japanese samples come with an English translation that keeps the model's slips. To write your own, use the demo.
公開モデルの未使用プロンプトに対するシード0の出力です。形式ごとにシード固定で無作為に選び、品質では選んでいません。日本語の例には、モデルの誤りを残したままの英訳を付けています。自分で試すにはデモをどうぞ。
English translation英訳
Weights, GGUF files, adapters, datasets and the demo.重み・GGUF・アダプタ・データセット・デモ。
Pipeline, training, evaluation, the report and this site.パイプライン・学習・評価・レポート・本サイト。
Trainer logs and system metrics for every run.全実行の学習ログとシステム指標。
Everything is Apache-2.0: the base model, the generators, the code, the adapters, the merged weights and the datasets.ベースモデル・生成モデル・コード・アダプタ・マージ済み重み・データセットはすべて Apache-2.0 です。
Transformers
from transformers import AutoModelForCausalLM, AutoTokenizer
repo = "whoashish115/Kitsune-Tales-E4B-EN"
tok = AutoTokenizer.from_pretrained(repo)
model = AutoModelForCausalLM.from_pretrained(
repo, torch_dtype="bfloat16", device_map="auto")
messages = [
{"role": "system", "content": SYSTEM_PROMPT}, # in the model card
{"role": "user", "content": "Genres: Slow Life, High Fantasy\n"
"Title: A Kicked-Out Summoner Wants a Quiet Life in the Frontier\n"
"Format: synopsis"},
]
ids = tok.apply_chat_template(messages, add_generation_prompt=True,
return_tensors="pt").to(model.device)
out = model.generate(ids, max_new_tokens=700, do_sample=True,
temperature=0.8, top_p=0.95, repetition_penalty=1.05)
print(tok.decode(out[0, ids.shape[1]:], skip_special_tokens=True))llama.cpp, 4-bit GGUF on CPUllama.cpp(4ビット GGUF、CPU)
llama-cli -m Kitsune-Tales-E4B-EN-Q4_K_M.gguf -st \ --temp 0.8 --top-p 0.95 -n 700 -p \ '<|turn>system You write original, general-audience fantasy light novels ...<turn|> <|turn>user Genres: Magical Girl Title: Magical Girl Lumina Is Late Again Today Format: synopsis<turn|> <|turn>model '
@misc{kumar2026kitsunetales,
title = {Kitsune Tales: Fantasy Light-Novel Fine-Tunes
of Gemma 4 E4B in Japanese and English},
author = {Kumar, Ashish},
year = {2026},
url = {https://github.com/whoashish115/kitsune-tales-qwen}
}